This revision: block scales chosen for accuracy
Each NVFP4 tensor stores a scale per 16 weights. ModelOpt's default takes it from the block's
largest weight; in this revision every block's scale is the one, of 21 from 0.60x to 1.10x of
that, that rounds the block closest to the BF16 weights. NVIDIA's build does the same on its NVFP4
tensors (only 28% of its scales are the default's). The layout, the size and the bytes read a
token are unchanged; the error of the 4-bit weights falls from 9.48% to 8.59%.
Greedy next-token agreement with BF16: each build reads BF16's own answers to 200 prompts
(coding, math, chat, tool use, multilingual; 46,706 answer tokens) and picks its next token at
every position, on vLLM 0.32.0 with the same settings for every build:
Table with columns: Build, Layout, Agrees with BF16, Coding| Build | Layout | Agrees with BF16 | Coding |
|---|
| BF16 itself (the engine's floor) | | 99.54% | 99.51% |
| nvidia/Qwen3.8-27B-NVFP4 | FP8 attention and DeltaNet | 94.33% | 94.58% |
| RadixArk/Qwen3.8-27B-NVFP4 | FP8 attention and DeltaNet | 93.73% | 93.47% |
| This revision | all NVFP4 | 93.00% | 92.98% |
The first revision (4a47ea5e) | all NVFP4 | 92.63% | 92.29% |
Keeping attention and DeltaNet in FP8 buys about a point of agreement for 3.16 GB more read a
token; the searched scales recover a third of that and read no more a token. The method, the tensor reading and
the scripts are in the
comparison.
Measured on one GB10
Through CapyCTL 0.1.10 on one NVIDIA GB10, temperature: 0,
thinking on, 512 tokens out; tokens/s, and at several streams the total:
Table with columns: Recipe, as its file ships, Revision, 1 stream, 8 streams, 32 streams (cap raised), Peak memory| Recipe, as its file ships | Revision | 1 stream | 8 streams | 32 streams (cap raised) | Peak memory |
|---|
| vLLM 0.32.0 with DFlash2 | this one | 33.9 | 177 | 390 with a 32 GiB KV cache (first revision) | 52.3 GiB |
| SGLang 0.5.22 with DFlash2 | the first (4a47ea5e) | 36.3 | 166 | 329 with a 94 GiB request | 58.1 GiB |
This revision against the first, through the same recipe files and accuracy sets:
Table with columns: vLLM: this revision, vLLM: first, SGLang: this revision, SGLang: first | vLLM: this revision | vLLM: first | SGLang: this revision | SGLang: first |
|---|
| 1 / 4 / 8 streams, total tokens/s | 33.5 / 101 / 177 | 34.9 / 103 / 187 | 31.3 / 103 / 162 | 35.9 / 106 / 166 |
| GSM8K, answers that finished in 2,048 tokens | 235/239 (98.3%) | 237/241 (98.3%) | 234/238 (98.3%) | 240/245 (98.0%) |
| Tool calls, 30 cases | 30/30 | 30/30 | 29/30 | 29/30 |
The DFlash2 drafter accepts fewer of its drafts on this revision's text (3.24 against 3.28
tokens a step on vLLM, 3.27 against 3.47 on SGLang at one stream); the layout, the size and
the kernels are the same. A same-day control puts about
2 of vLLM's 5 points at 8 streams down to the day. The vLLM recipe uses this revision; the SGLang
recipe keeps the first, where this one cost 13% on one stream.
Against nvidia/Qwen3.8-27B-NVFP4 on the same engine and settings, measured with the first
revision:
Table with columns: This checkpoint, first revision, nvidia/Qwen3.8-27B-NVFP4 | This checkpoint, first revision | nvidia/Qwen3.8-27B-NVFP4 |
|---|
vLLM 0.32.0 with DFlash2 (z-lab/Qwen3.8-27B-DFlash2), DeltaNet state cache bf16: 1 / 8 streams | 35.7 / 181 (+23% / +13%) | 29.0 / 160 |
| SGLang 0.5.22 with DFlash2, bf16 DeltaNet state, two decode steps a round: 1 / 8 streams | 35.2 / 166 (+16% / +10%) | 30.4 / 150 |
| SGLang 0.5.22, no drafts: 1 / 8 streams | 14.9 / 101 (+19% / +18%) | 12.5 / 85.9 |
| GSM8K, 250 test questions, answers that finished in 2,048 tokens | 98.3% | 98.4% |
| Tool calls, 30 cases | 30/30 | 30/30 |
The BF16 source scores 98.3% on the same GSM8K answers. The DFlash2 drafter accepts the same
number of drafted tokens a round on the first revision and NVIDIA's checkpoint, so that gain is
the cheaper verify step.
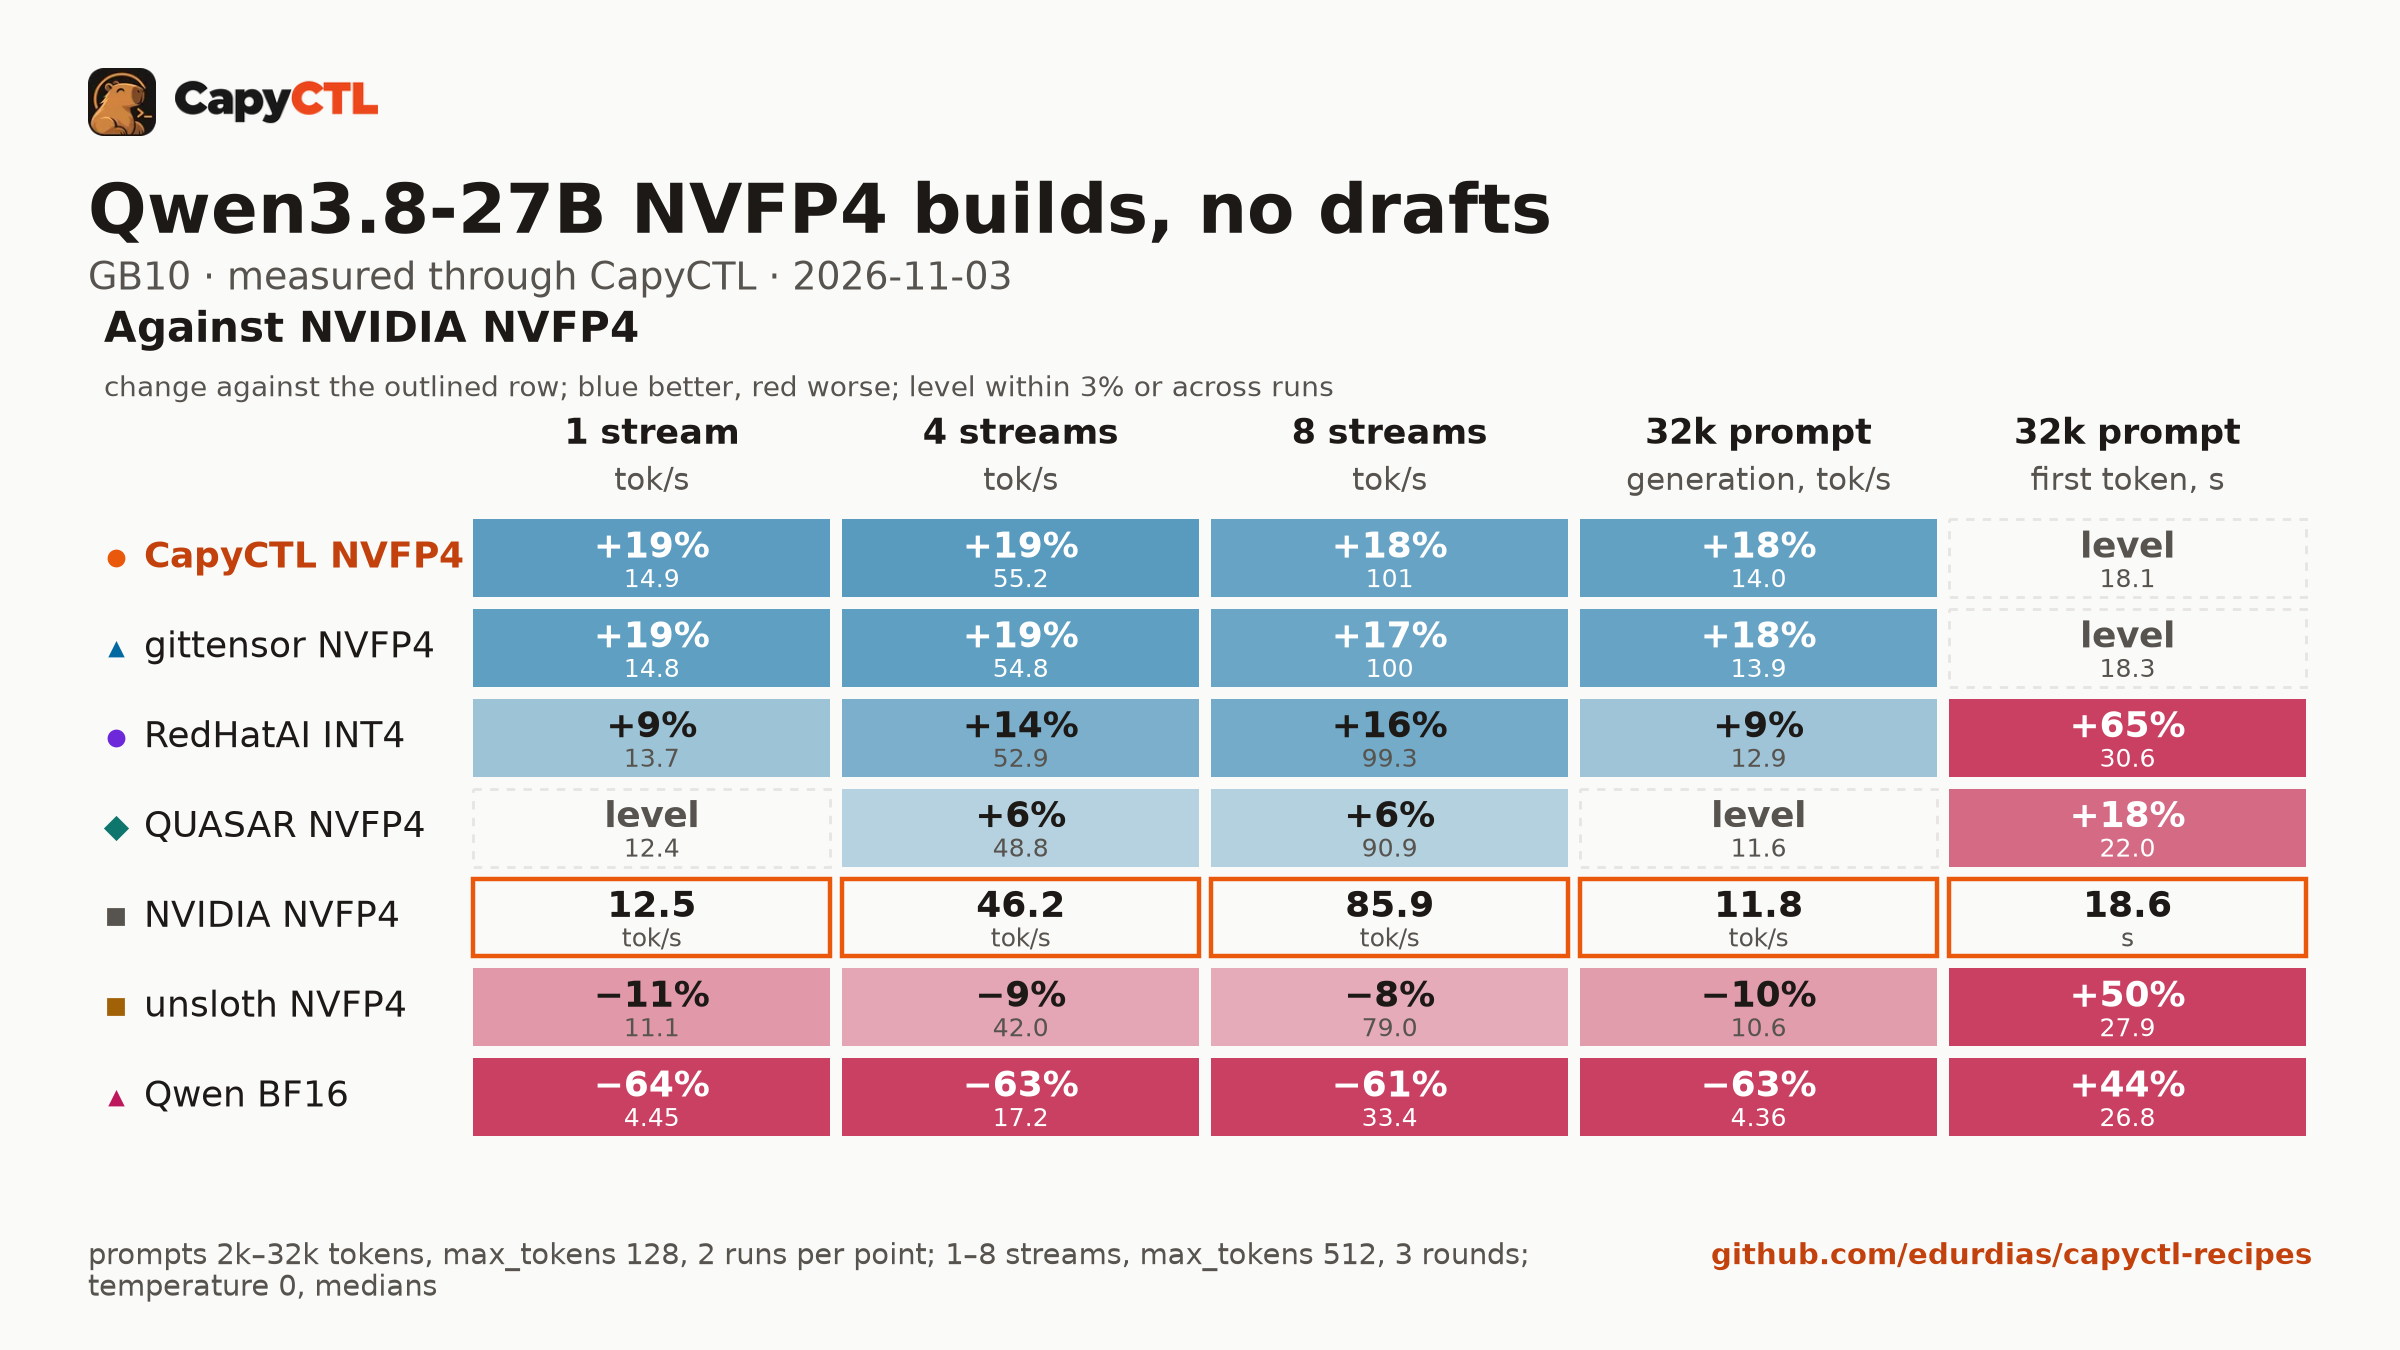
The comparison
measures it against NVIDIA's, gittensor's, QUASAR's, RedHatAI's and unsloth's builds, the BF16
source and MiaAI-Lab's EXL3, with and without DFlash2, and holds the settings sweep, the
accuracy answers and every results file. gittensor's build has the same layout without the MTP
head and is as fast.
Run it with CapyCTL
Install CapyCTL and
register a vLLM 0.32.0 environment,
allowing the drafter option for a directory of drafters, then download the drafter (CapyCTL
does not download drafters):
capyctl engine add ~/vllm-0.32.0-venv \ --approve-option=--speculative-config --approve-path ~/draftershf download z-lab/Qwen3.8-27B-DFlash2 \ --revision 50307d4c4cde6860d4eee73e2547cd786fe8e8a4 \ --local-dir ~/drafters/Qwen3.8-27B-DFlash2
Start CapyCTL on the machine and leave it running
(Run on one machine):
In a second terminal, deploy the recipe's
deployment.yaml
(change the drafter path in it to yours). CapyCTL downloads this checkpoint, pinned to its
commit, and serves it on its OpenAI-compatible endpoint:
capyctl deploy model --file deployment.yamlcapyctl start deployment qwen38-27b-capyctl-nvfp4-vllm --wait
Deploy a model explains the file. The
SGLang recipe
does the same on SGLang 0.5.22 with the first revision (4a47ea5e). The checkpoint is in
ModelOpt's NVFP4 format, as NVIDIA's is; only vLLM 0.32.0 and SGLang 0.5.22 were measured with it.
How it was made
convert/
in that recipe rebuilds it: ModelOpt 0.47.0 examples/hf_ptq/hf_ptq.py with the
recipe qwen3_5-nvfp4_all_linear-kv_none.yaml, max calibration on 512
conversations of up to 1024 tokens (256 from HuggingFaceH4/ultrachat_200k, 256
from ise-uiuc/Magicoder-OSS-Instruct-75K, both MIT), then an audit of every
tensor's format. requant_scales.py then re-rounds every NVFP4 weight from the BF16 source with
the searched block scales, keeping the per-tensor and input scales. conversion-manifest.json
records the source revision, the tools and their versions, the SHA-256 of the recipe, the
calibration set, the converter and the scale-search scripts, and requant-scales.json each
tensor's error before and after.
License
Apache 2.0, as the base model.