Usage
Designed for use with the tcclaviger/vllm-rocm-rdna4-mxfp4 Docker image on AMD RDNA4 GPUs (Radeon AI PRO R9700).
vllm serve pahajokiconsulting/Qwen3.6-35B-A3B-MXFP4 \ --tensor-parallel-size 2 \ --max-model-len 32768 \ --reasoning-parser qwen3 \ --tool-call-parser qwen3_xml \ --num-speculative-tokens 4 \ --port 8000
Leave CUDA graphs on (i.e. do not pass --enforce-eager) for best decode throughput. The vision tower is retained in BF16, so --language-model-only is not required.
Speculative decoding (MTP)
The quant is prepared so Qwen3.6's built-in MTP (multi-token prediction) draft model loads correctly: the mtp.* block is kept in BF16 with per-expert .weight tensors, which is the layout stock vLLM's MTP loader expects. Run with --num-speculative-tokens 4 to activate it.
Hardware tested
- 2× AMD Radeon AI PRO R9700 (64 GB total VRAM), TP=2
- Peak model VRAM: 13.38 GiB per rank after MTP draft load
Throughput (single-request decode)
Measured on a 16k-token completion, TP=2, MTP with 4 draft tokens:
Table with columns: Metric, Value| Metric | Value |
|---|
| Generation throughput | ~153 tokens/s |
| Mean MTP acceptance length | 4.25 / 4 |
| Average draft acceptance | 81.2% |
| Per-position acceptance | 93.1% / 85.3% / 75.9% / 70.4% |
First request after server start is slower (Triton kernel JIT + TunableOps warmup). Throughput climbs into steady state over a few requests.
For reference, our earlier Qwen3.5-35B-A3B MXFP4 release peaked at 101 t/s after a two-hour dedicated TunableOps tuning pass on the same hardware. The 3.6 number above was observed with no Qwen3.6-specific tuning — TunableOps entries from the 3.5 run carry over because both models share the same GEMM shape profile. Running a dedicated 3.6 tuning pass is likely to push this higher.
Quantization details
- Tool: olka/qstream (stock v0.1.0 produces a broken output for Qwen3.6 — a fix to the default exclude list and to 3D-fused passthrough handling is required, see PR linked in that repo)
- Input: BF16 (
Qwen/Qwen3.6-35B-A3B)
- Output: compressed-tensors MXFP4, CT per-expert format
- MSE-optimal scale selection enabled
- Size: 71.9 GB → 23.1 GB (~32%)
What is MXFP4, what is BF16
The following are kept in BF16 (not quantized) — quantizing any of these breaks loading against stock vLLM:
model.embed_tokens, lm_headmodel.language_model.layers.*.self_attn.* and linear_attn.{conv1d,norm}model.language_model.layers.*.mlp.gate (routing gate)model.language_model.layers.*.mlp.shared_expert_gate (shape [1, 2048] — not a Linear)model.language_model.layers.*.mlp.shared_expert.{gate,up,down}_proj (shared expert FFN)model.visual.* — entire vision tower (attention, MLP, merger, pos_embed, patch_embed)
Quantized to MXFP4 (CT per-expert, .weight_packed + .weight_scale):
model.language_model.layers.*.linear_attn.in_proj_{a,b,qkv,z} and out_projmodel.language_model.layers.*.mlp.experts.{i}.{gate,up,down}_proj — all 256 experts
Why the extended exclude list
Qwen3.6 introduces a shared_expert_gate submodule that Qwen3.5 also has, but whose name doesn't match qstream's default *.mlp.gate. pattern. Attempting to quantize it produces shared_expert_gate.weight_packed / .weight_scale tensors that vLLM's loader silently skips (not found in params_dict), leaving the shared-expert gate uninitialized and producing garbage output. The vision tower and MTP block have analogous issues — vLLM expects those modules to be BF16 dense, not compressed-tensors. The working Qwen3.5 MXFP4 release kept all of these in BF16; this release does the same.
Qwen3.6-35B-A3B

[!Note]
This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
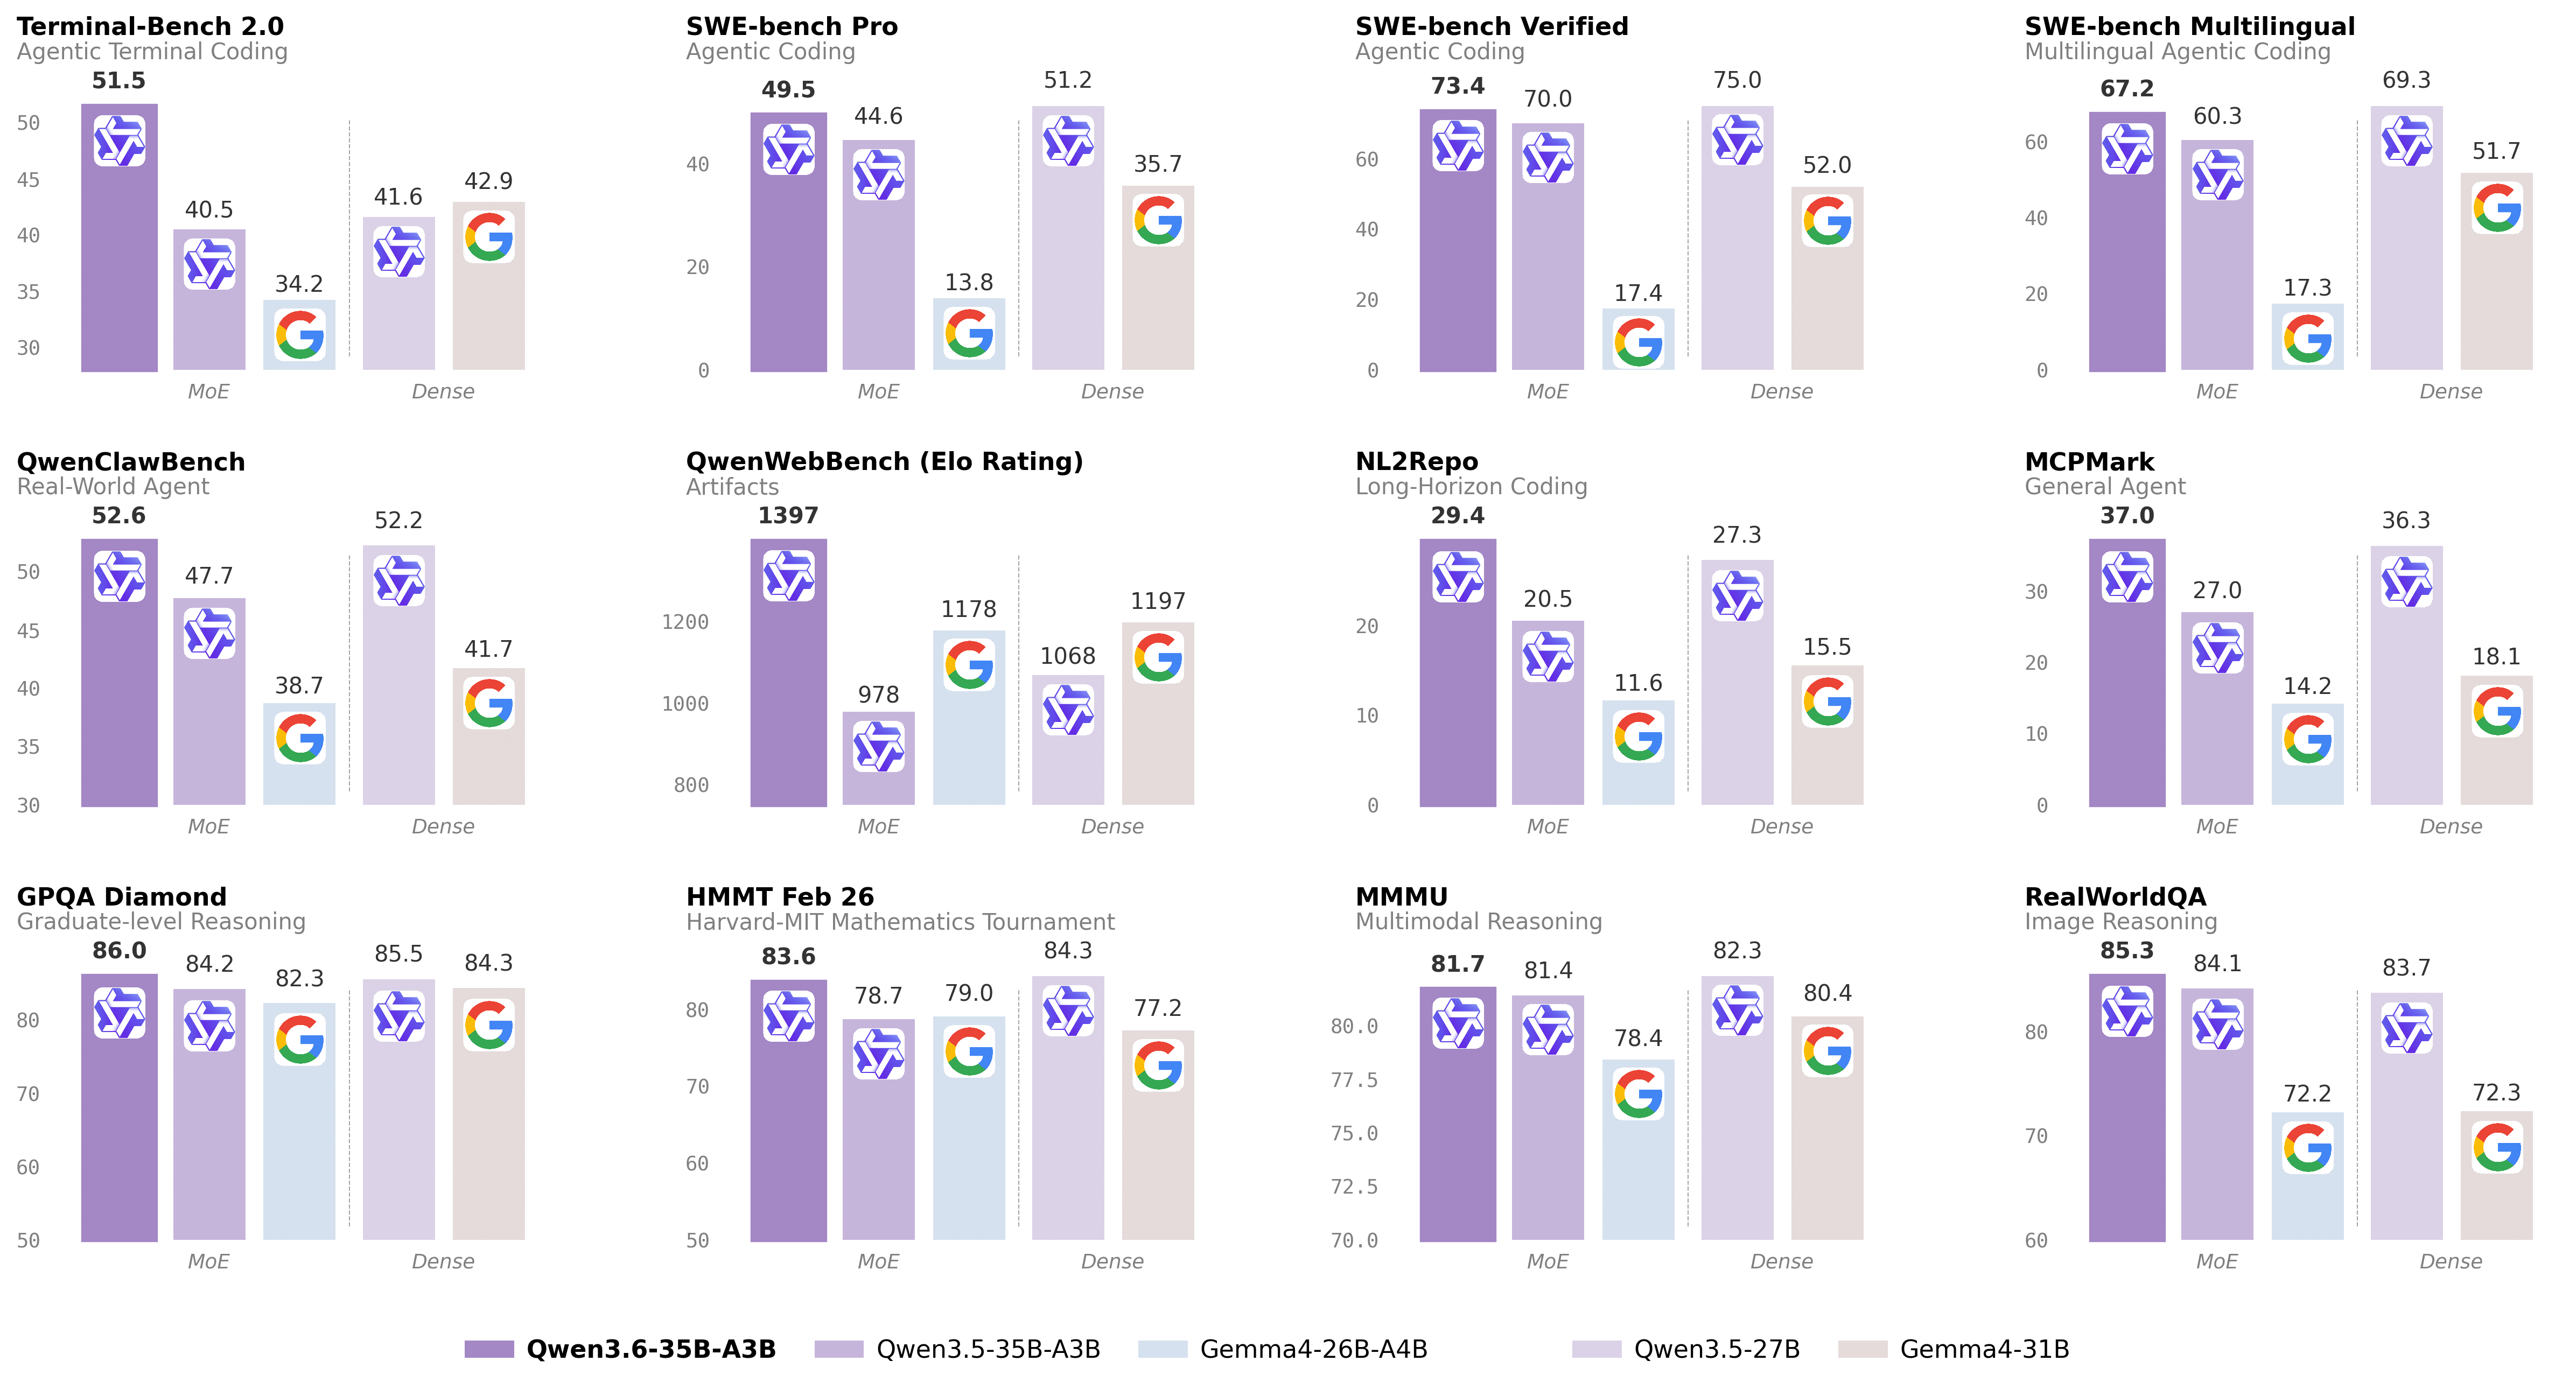
For more details, please refer to our blog post Qwen3.6-35B-A3B.
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 35B in total and 3B activated
- Hidden Dimension: 2048
- Token Embedding: 248320 (Padded)
- Number of Layers: 40
- Hidden Layout: 10 × (3 × (Gated DeltaNet → MoE) → 1 × (Gated Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 32 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 16 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
Benchmark Results
Language
Vision Language
Quickstart
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Serving Qwen3.6
Qwen3.6 can be served via APIs with popular inference frameworks.
In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
[!Important]
Inference efficiency and throughput vary significantly across frameworks.
We recommend using the latest framework versions to ensure optimal performance and compatibility.
For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
[!Important]
The model has a default context length of 262,144 tokens.
If you encounter out-of-memory (OOM) errors, consider reducing the context window.
However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang
SGLang is a fast serving framework for large language models and vision language models.
sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install sglang[all]
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-35B-A3B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3
-
Tool Use: To support tool use, you can use the following command.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-35B-A3B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --tool-call-parser qwen3_coder
-
Multi-Token Prediction (MTP): The following command is recommended for MTP:
python -m sglang.launch_server --model-path Qwen/Qwen3.6-35B-A3B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --speculative-algo NEXTN --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4
For detailed deployment guide, see the SGLang Qwen3.5 Cookbook.
vLLM
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs.
vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install vllm --torch-backend=auto
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3
-
Tool Call: To support tool use, you can use the following command.
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder
-
Multi-Token Prediction (MTP): The following command is recommended for MTP:
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --speculative-config '{"method":"qwen3_next_mtp","num_speculative_tokens":2}'
-
Text-Only: The following command skips the vision encoder and multimodal profiling to free up memory for additional KV cache:
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --language-model-only
For detailed deployment guide, see the vLLM Qwen3.5 Recipe.
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing.
For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment.
The latest transformers is required for Qwen3.6:
pip install "transformers[serving]"
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
transformers serve Qwen/Qwen3.6-35B-A3B --port 8000 --continuous-batching
Using Qwen3.6 via the Chat Completions API
The chat completions API is accessible via standard HTTP requests or OpenAI SDKs.
Here, we show examples using the OpenAI Python SDK.
Before starting, make sure it is installed and the API key and the API base URL is configured, e.g.:
pip install -U openai # Set the following accordinglyexport OPENAI_BASE_URL="http://localhost:8000/v1"export OPENAI_API_KEY="EMPTY"
[!Tip]
We recommend using the following set of sampling parameters for generation
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
- Thinking mode for precise coding tasks (e.g. WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Instruct (or non-thinking) mode for general tasks:
temperature=0.7, top_p=0.8, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
- Instruct (or non-thinking) mode for reasoning tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
Please note that the support for sampling parameters varies according to inference frameworks.
[!Important]
Qwen3.6 models operate in thinking mode by default, generating thinking content signified by <think>\n...</think>\n\n before producing the final responses.
To disable thinking content and obtain direct response, refer to the examples here.
Text-Only Input
from openai import OpenAI# Configured by environment variablesclient = OpenAI() messages = [ {"role": "user", "content": "Type \"I love Qwen3.6\" backwards"},] chat_response = client.chat.completions.create( model="Qwen/Qwen3.6-35B-A3B", messages=messages, max_tokens=81920, temperature=1.0, top_p=0.95, presence_penalty=1.5, extra_body={ "top_k": 20, }, )print("Chat response:", chat_response)
from openai import OpenAI# Configured by environment variablesclient = OpenAI() messages = [ { "role": "user", "content": [ { "type": "image_url", "image_url": { "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg" } }, { "type": "text", "text": "The centres of the four illustrated circles are in the corners of the square. The two big circles touch each other and also the two little circles. With which factor do you have to multiply the radii of the little circles to obtain the radius of the big circles?\nChoices:\n(A) $\\frac{2}{9}$\n(B) $\\sqrt{5}$\n(C) $0.8 \\cdot \\pi$\n(D) 2.5\n(E) $1+\\sqrt{2}$" } ] }] response = client.chat.completions.create( model="Qwen/Qwen3.6-35B-A3B", messages=messages, max_tokens=81920, temperature=1.0, top_p=0.95, presence_penalty=1.5, extra_body={ "top_k": 20, }, )print("Chat response:", chat_response)
from openai import OpenAI# Configured by environment variablesclient = OpenAI() messages = [ { "role": "user", "content": [ { "type": "video_url", "video_url": { "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/video/N1cdUjctpG8.mp4" } }, { "type": "text", "text": "How many porcelain jars were discovered in the niches located in the primary chamber of the tomb?" } ] }] # When vLLM is launched with `--media-io-kwargs '{"video": {"num_frames": -1}}'`,# video frame sampling can be configured via `extra_body` (e.g., by setting `fps`).# This feature is currently supported only in vLLM.## By default, `fps=2` and `do_sample_frames=True`.# With `do_sample_frames=True`, you can customize the `fps` value to set your desired video sampling rate.response = client.chat.completions.create( model="Qwen/Qwen3.6-35B-A3B", messages=messages, max_tokens=81920, temperature=1.0, top_p=0.95, presence_penalty=1.5, extra_body={ "top_k": 20, "mm_processor_kwargs": {"fps": 2, "do_sample_frames": True}, }, ) print("Chat response:", chat_response)
Instruct (or Non-Thinking) Mode
[!Important]
Qwen3.6 does not officially support the soft switch of Qwen3, i.e., /think and /nothink.
Qwen3.6 will think by default before response.
You can obtain direct response from the model without thinking by configuring the API parameters.
For example,
from openai import OpenAI# Configured by environment variablesclient = OpenAI() messages = [ { "role": "user", "content": [ { "type": "image_url", "image_url": { "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.6/demo/RealWorld/RealWorld-04.png" } }, { "type": "text", "text": "Where is this?" } ] }] chat_response = client.chat.completions.create( model="Qwen/Qwen3.6-35B-A3B", messages=messages, max_tokens=32768, temperature=0.7, top_p=0.8, presence_penalty=1.5, extra_body={ "top_k": 20, "chat_template_kwargs": {"enable_thinking": False}, }, )print("Chat response:", chat_response)
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changing model, please use "enable_thinking": False instead of "chat_template_kwargs": {"enable_thinking": False}.
Preserve Thinking
By default, only the thinking blocks generated in handling the latest user message is retained, resulting in a pattern commonly as interleaved thinking.
Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages.
You can enable this behavior by setting the preserve_thinking option:
from openai import OpenAI# Configured by environment variablesclient = OpenAI() messages = [...] chat_response = client.chat.completions.create( model="Qwen/Qwen3.6-35B-A3B", messages=messages, max_tokens=32768, temperature=0.7, top_p=0.8, presence_penalty=1.5, extra_body={ "top_k": 20, "chat_template_kwargs": {"preserve_thinking": True}, }, )print("Chat response:", chat_response)
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changing model, please use "preserve_thinking": True instead of "chat_template_kwargs": {"preserve_thinking": False}.
This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency and, in many cases, reduce overall token consumption by minimizing redundant reasoning. Additionally, it can improve KV cache utilization, optimizing inference efficiency in both thinking and non-thinking modes.
Agentic Usage
Qwen3.6 excels in tool calling capabilities.
Qwen-Agent
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
import osfrom qwen_agent.agents import Assistant # Define LLM# Using Alibaba Cloud Model Studiollm_cfg = { # Use the OpenAI-compatible model service provided by DashScope: 'model': 'Qwen3.6-35B-A3B', 'model_type': 'qwenvl_oai', 'model_server': 'https://dashscope.aliyuncs.com/compatible-mode/v1', 'api_key': os.getenv('DASHSCOPE_API_KEY'), 'generate_cfg': { 'use_raw_api': True, # When using Dash Scope OAI API, pass the parameter of whether to enable thinking mode in this way 'extra_body': { 'enable_thinking': True, 'preserve_thinking': True, }, },} # Using OpenAI-compatible API endpoint.# functionality of the deployment frameworks and let Qwen-Agent automate the related operations.## llm_cfg = {# # Use your own model service compatible with OpenAI API by vLLM/SGLang:# 'model': 'Qwen/Qwen3.6-35B-A3B',# 'model_type': 'qwenvl_oai',# 'model_server': 'http://localhost:8000/v1', # api_base# 'api_key': 'EMPTY',## 'generate_cfg': {# 'use_raw_api': True,# # When using vLLM/SGLang OAI API, pass the parameter of whether to enable thinking mode in this way# 'extra_body': {# 'chat_template_kwargs': {'enable_thinking': True, 'preserve_thinking': True}# },# },# } # Define Toolstools = [ {'mcpServers': { # You can specify the MCP configuration file "filesystem": { "command": "npx", "args": ["-y", "@modelcontextprotocol/server-filesystem", "/Users/xxxx/Desktop"] } } }] # Define Agentbot = Assistant(llm=llm_cfg, function_list=tools) # Streaming generationmessages = [{'role': 'user', 'content': 'Help me organize my desktop.'}]for responses in bot.run(messages=messages): passprint(responses) # Streaming generationmessages = [{'role': 'user', 'content': 'Develop a dog website and save it on the desktop'}]for responses in bot.run(messages=messages): passprint(responses)
Qwen Code
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
For more information, please refer to Qwen Code.
Processing Ultra-Long Texts
Qwen3.6 natively supports context lengths of up to 262,144 tokens.
For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang.
In general, there are two approaches to enabling YaRN for supported frameworks:
-
Modifying the model configuration file:
In the config.json file, change the rope_parameters fields in text_config to:
{ "mrope_interleaved": true, "mrope_section": [ 11, 11, 10 ], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144,}
-
Passing command line arguments:
For vllm, you can use
VLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1010000
For sglang and ktransformers, you can use
SGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python -m sglang.launch_server ... --json-model-override-args '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --context-length 1010000
[!NOTE]
All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts.
We advise modifying the rope_parameters configuration only when processing long contexts is required.
It is also recommended to modify the factor as needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to set factor as 2.0.
Best Practices
To achieve optimal performance, we recommend the following settings:
-
Sampling Parameters:
- We suggest using the following sets of sampling parameters depending on the mode and task type:
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
- Thinking mode for precise coding tasks (e.g., WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0,
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen36_35b_a3b, title = {{Qwen3.6-35B-A3B}: Agentic Coding Power, Now Open to All}, url = {https://qwen.ai/blog?id=qwen3.6-35b-a3b}, author = {{Qwen Team}}, month = {April}, year = {2026}}